Speech to prompt
In CodeAlta Desktop you can dictate a prompt. A speech model that runs on your computer writes what you say at the caret. Your voice never leaves your computer.
Dictate a prompt
Click the microphone beside Send, or press F9, and speak. The button turns red and follows your voice. It is in the prompt of a session and of a new session.
- What is being recognized shows in grey at the caret, and can still change.
- Each pause writes the sentence into the prompt, as one edit:
Ctrl+Zremoves it. - Click the button again, or press
F9orEsc, to stop; the last words are written too. Enter(or Send) while dictating finishes the sentence and sends the prompt.- After 30 seconds of silence, dictation stops by itself; what was said stays.
Dictated text is ordinary prompt text: correct it and send it as usual. File, function and command names are often misheard, so read them first.
First use
The first press shows a small setup beside the button and records nothing yet:
- Microphone: the input device, with a level bar. If the bar stays flat when you speak, choose another device: the system default is not always the one you talk into.
- Model: the speech model and its size, with a link to choose another.
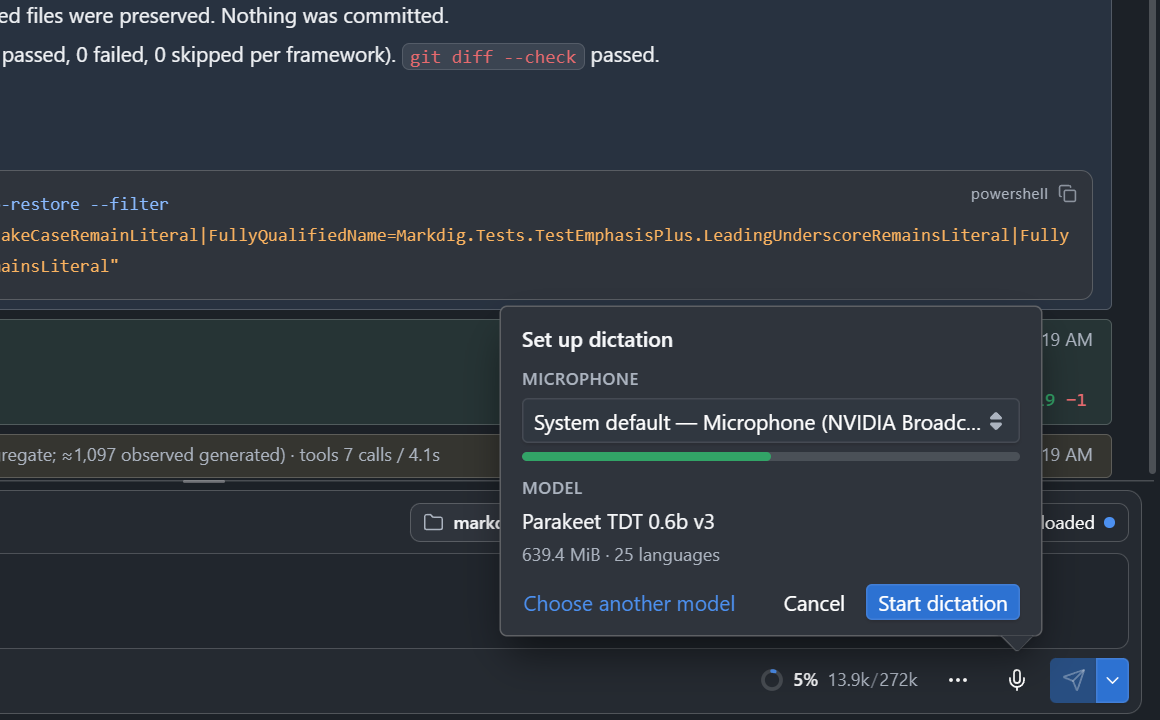
Start dictation keeps that microphone and starts; it reads Download while the model is missing. After that, the button records at once.
Nothing is downloaded before you ask. A notification shows the download, with Cancel; you can keep working, and an interrupted download resumes next time. The first download brings the model, from Hugging Face, and the speech engine (sherpa-onnx, about 10 MiB), from nuget.org. Every file is checked against its checksum.
Settings
Settings > Personalization > Speech:
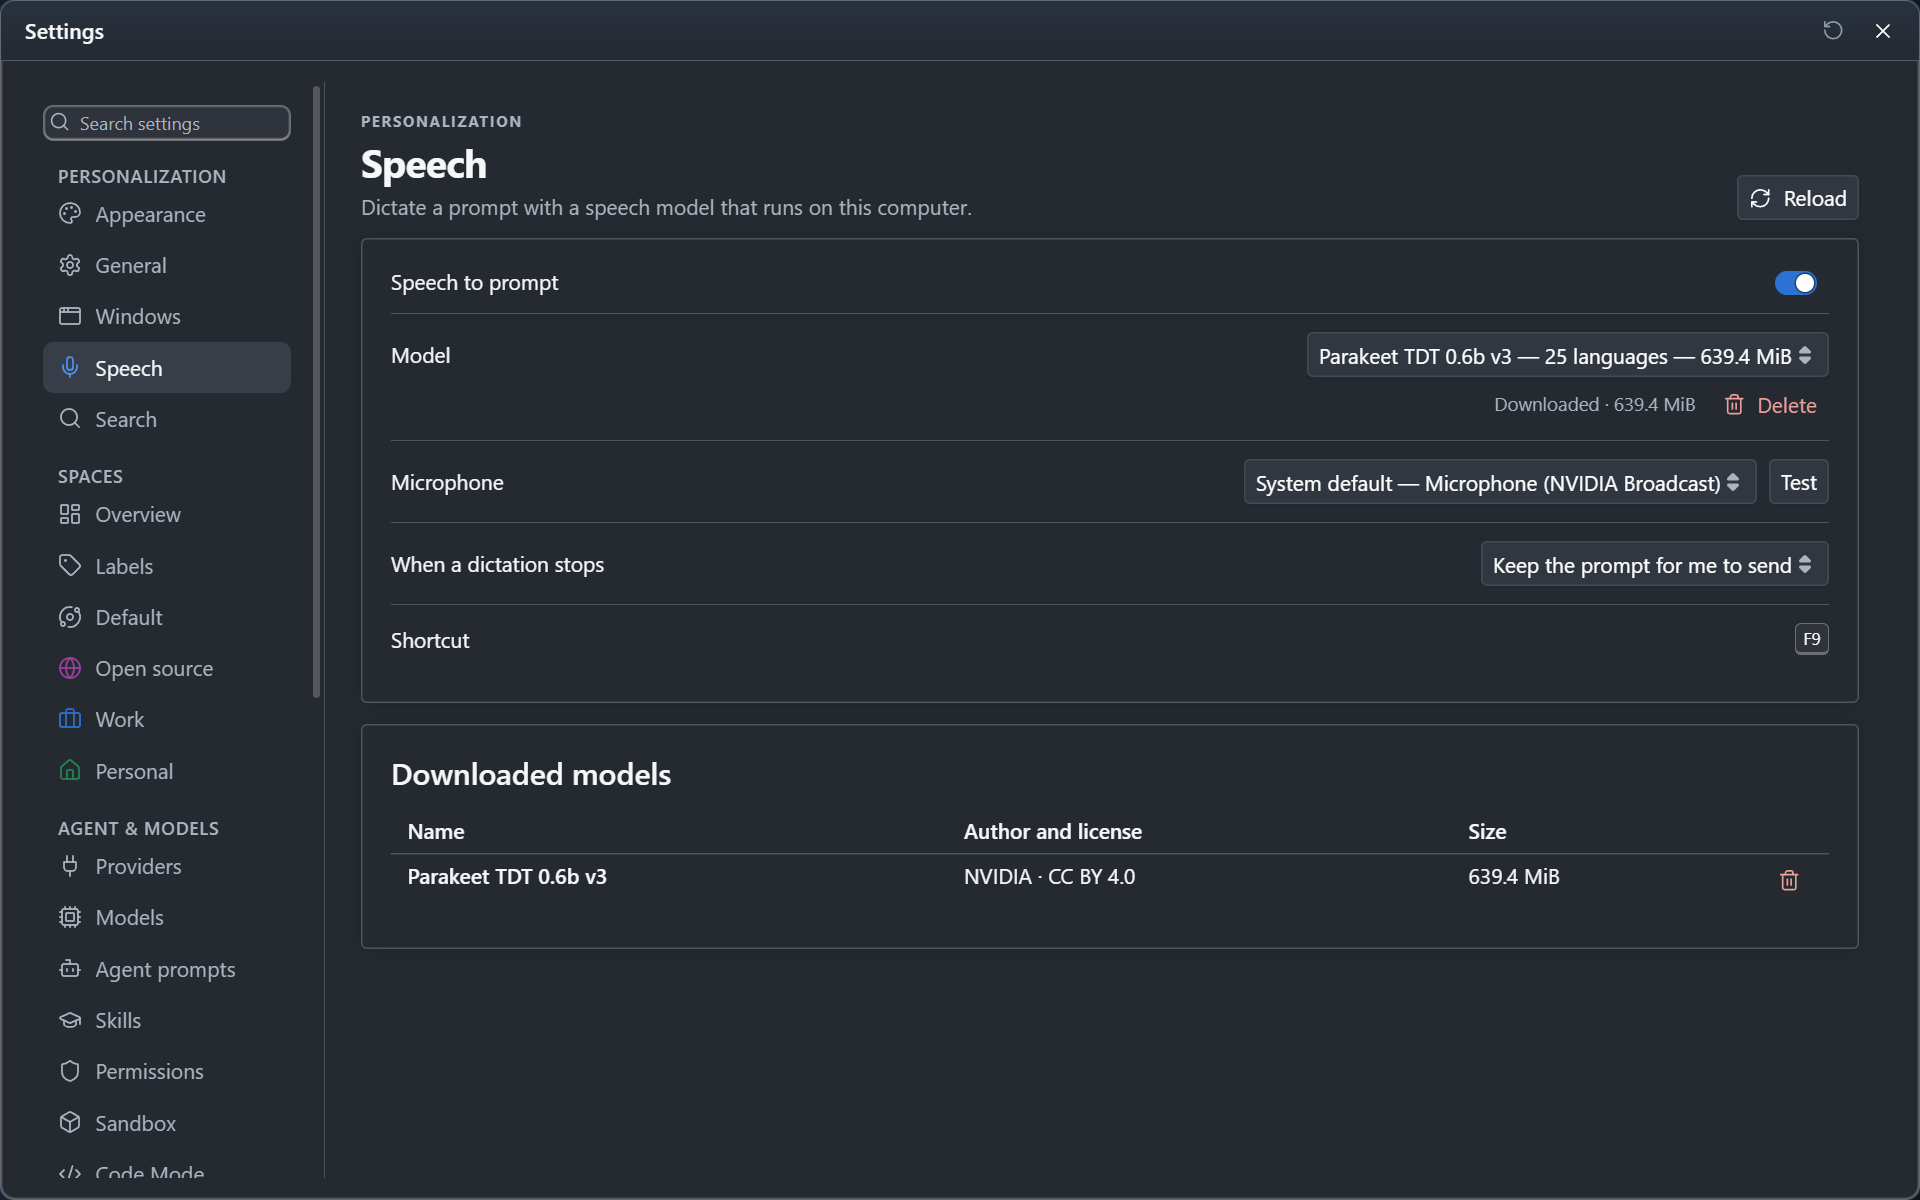
| Setting | What it does |
|---|---|
| Speech to prompt | On or off. Off, there is no microphone button and CodeAlta never asks for the microphone. |
| Model | The speech model and its state: to download, downloading, or downloaded with a delete button. |
| Microphone | The input device. Test shows its level. |
| When a dictation stops | Keep the prompt for me to send (default) or Send the prompt. |
| Downloaded models | Models on your computer, with their size and a delete button. |
Sending. With Send the prompt, stopping with the button or F9 sends the prompt when at least three words were dictated. Esc stops without sending, and a dictation that stops by itself (silence, another tab) never sends. In both modes, Enter during dictation sends.
Microphone. Each window keeps its own choice (the normal and developer instances too). When the chosen microphone is not connected, CodeAlta uses the system one and tells you. When a dictation hears nothing at first, CodeAlta offers to choose another microphone.
Models
| Model | Languages | Download | From | model |
|---|---|---|---|---|
| Parakeet TDT 0.6b v3 (default) | 25 European languages, detected | 639 MiB | NVIDIA, CC BY 4.0 | parakeet-tdt-0.6b-v3 |
| Parakeet TDT 0.6b v2 | English | 631 MiB | NVIDIA, CC BY 4.0 | parakeet-tdt-0.6b-v2 |
| Whisper small | 99 languages | 358 MiB | OpenAI, MIT | whisper-small |
| Moonshine base | English | 135 MiB | Moonshine AI, MIT | moonshine-base-en |
| Moonshine tiny | English | 42 MiB | Moonshine AI, MIT | moonshine-tiny-en |
The Parakeet models are the most accurate and write punctuation and capitals. The Moonshine models are much smaller, for a quick download or a slow computer.
A model of your own
Choose Custom and give a Hugging Face repository address (https://huggingface.co/<owner>/<repository>) or one of its folders (.../tree/<revision>/<folder>). CodeAlta recognizes these sherpa-onnx models:
- a transducer:
encoder*.onnx,decoder*.onnx,joiner*.onnxandtokens.txt; - Moonshine:
encoder_model.*,decoder_model_merged.*andtokens.txt, or the four files of its first version; - Whisper:
<name>-encoder*.onnx,<name>-decoder*.onnxand<name>-tokens.txt; - SenseVoice or Paraformer: one
model*.onnxandtokens.txt, in a repository or folder whose name sayssense-voiceorparaformer; - FireRedASR:
encoder*.onnx,decoder*.onnxandtokens.txt, in a repository whose name saysfire-red.
SenseVoice finds the language by itself: Chinese, English, Japanese, Korean or Cantonese.
Quantized (int8) files are preferred. A repository with none of these is refused before download. A model the engine cannot load is reported after download, and can be deleted on the same page.
Files and configuration
- Models are in
~/.alta/cache/speech, the engine in~/.alta/cache/runtime(shared with search by meaning). Both can be deleted: they download again when needed. - The model stays in memory a few minutes after a dictation, then the memory is given back.
The choices are in [speech] of ~/.alta/config.toml, except the microphone, which belongs to the window. Defaults are not written:
[speech]
enabled = false          # true when absent
model = "whisper-small"  # a model of the table above, or the address of a repository
send = "on_stop"         # "manual" when absent: the prompt stays for you to send
System permission
The first time, the system may ask whether CodeAlta can use the microphone.
- Windows: Settings > Privacy & security > Microphone > Let desktop apps access your microphone must be on.
- macOS: allow CodeAlta in System Settings > Privacy & Security > Microphone. Started from a terminal, CodeAlta uses the terminal's permission.
- Linux: the microphone goes through WebKitGTK, which needs PipeWire or PulseAudio. Without one, there is no microphone button.